CASE STUDY DETAILS
AI & Sales Analytics Platform
Project Type
Analytics
Challenge
Fragmentation
Domain
Retail
Impact
Visibility
OVERVIEW
The project is an automated document processing and enterprise data management platform that combines Python-based document extraction, and Snowflake Cloud Data Warehouse.
The platform automates the complete journey of business documents—from PDF/image ingestion and information extraction to data validation, transformation, centralized storage, and analytics.
It is designed to reduce manual document processing, improve data quality, and provide a reliable centralized data layer for downstream reporting and business operations.
PROBLEM
The existing/manual approach created several operational challenges
The business process involved handling a large number of invoices/documents that could contain both machine-readable text and scanned images.
- Employees had to manually extract information from documents.
- Data Quality Challenges
- Data Management Challenges
- Raw document information was not immediately available in a centralised analytical platform
SOLUTIONS
1. Layered Snowflake Data Architecture
- A four-layer pipeline (Raw → Staging → Analytics → Marts) that separates landing, cleaning, modeling, and business consumption — so every layer has one clear job and issues are traceable to their source.
3. Kimball-Style Star Schema
- Snowflake Streams and Tasks automatically detect and propagate only new or changed data, keeping the platform current without manual reprocessing or full-table reloads.
5. Governed Data Quality Framework
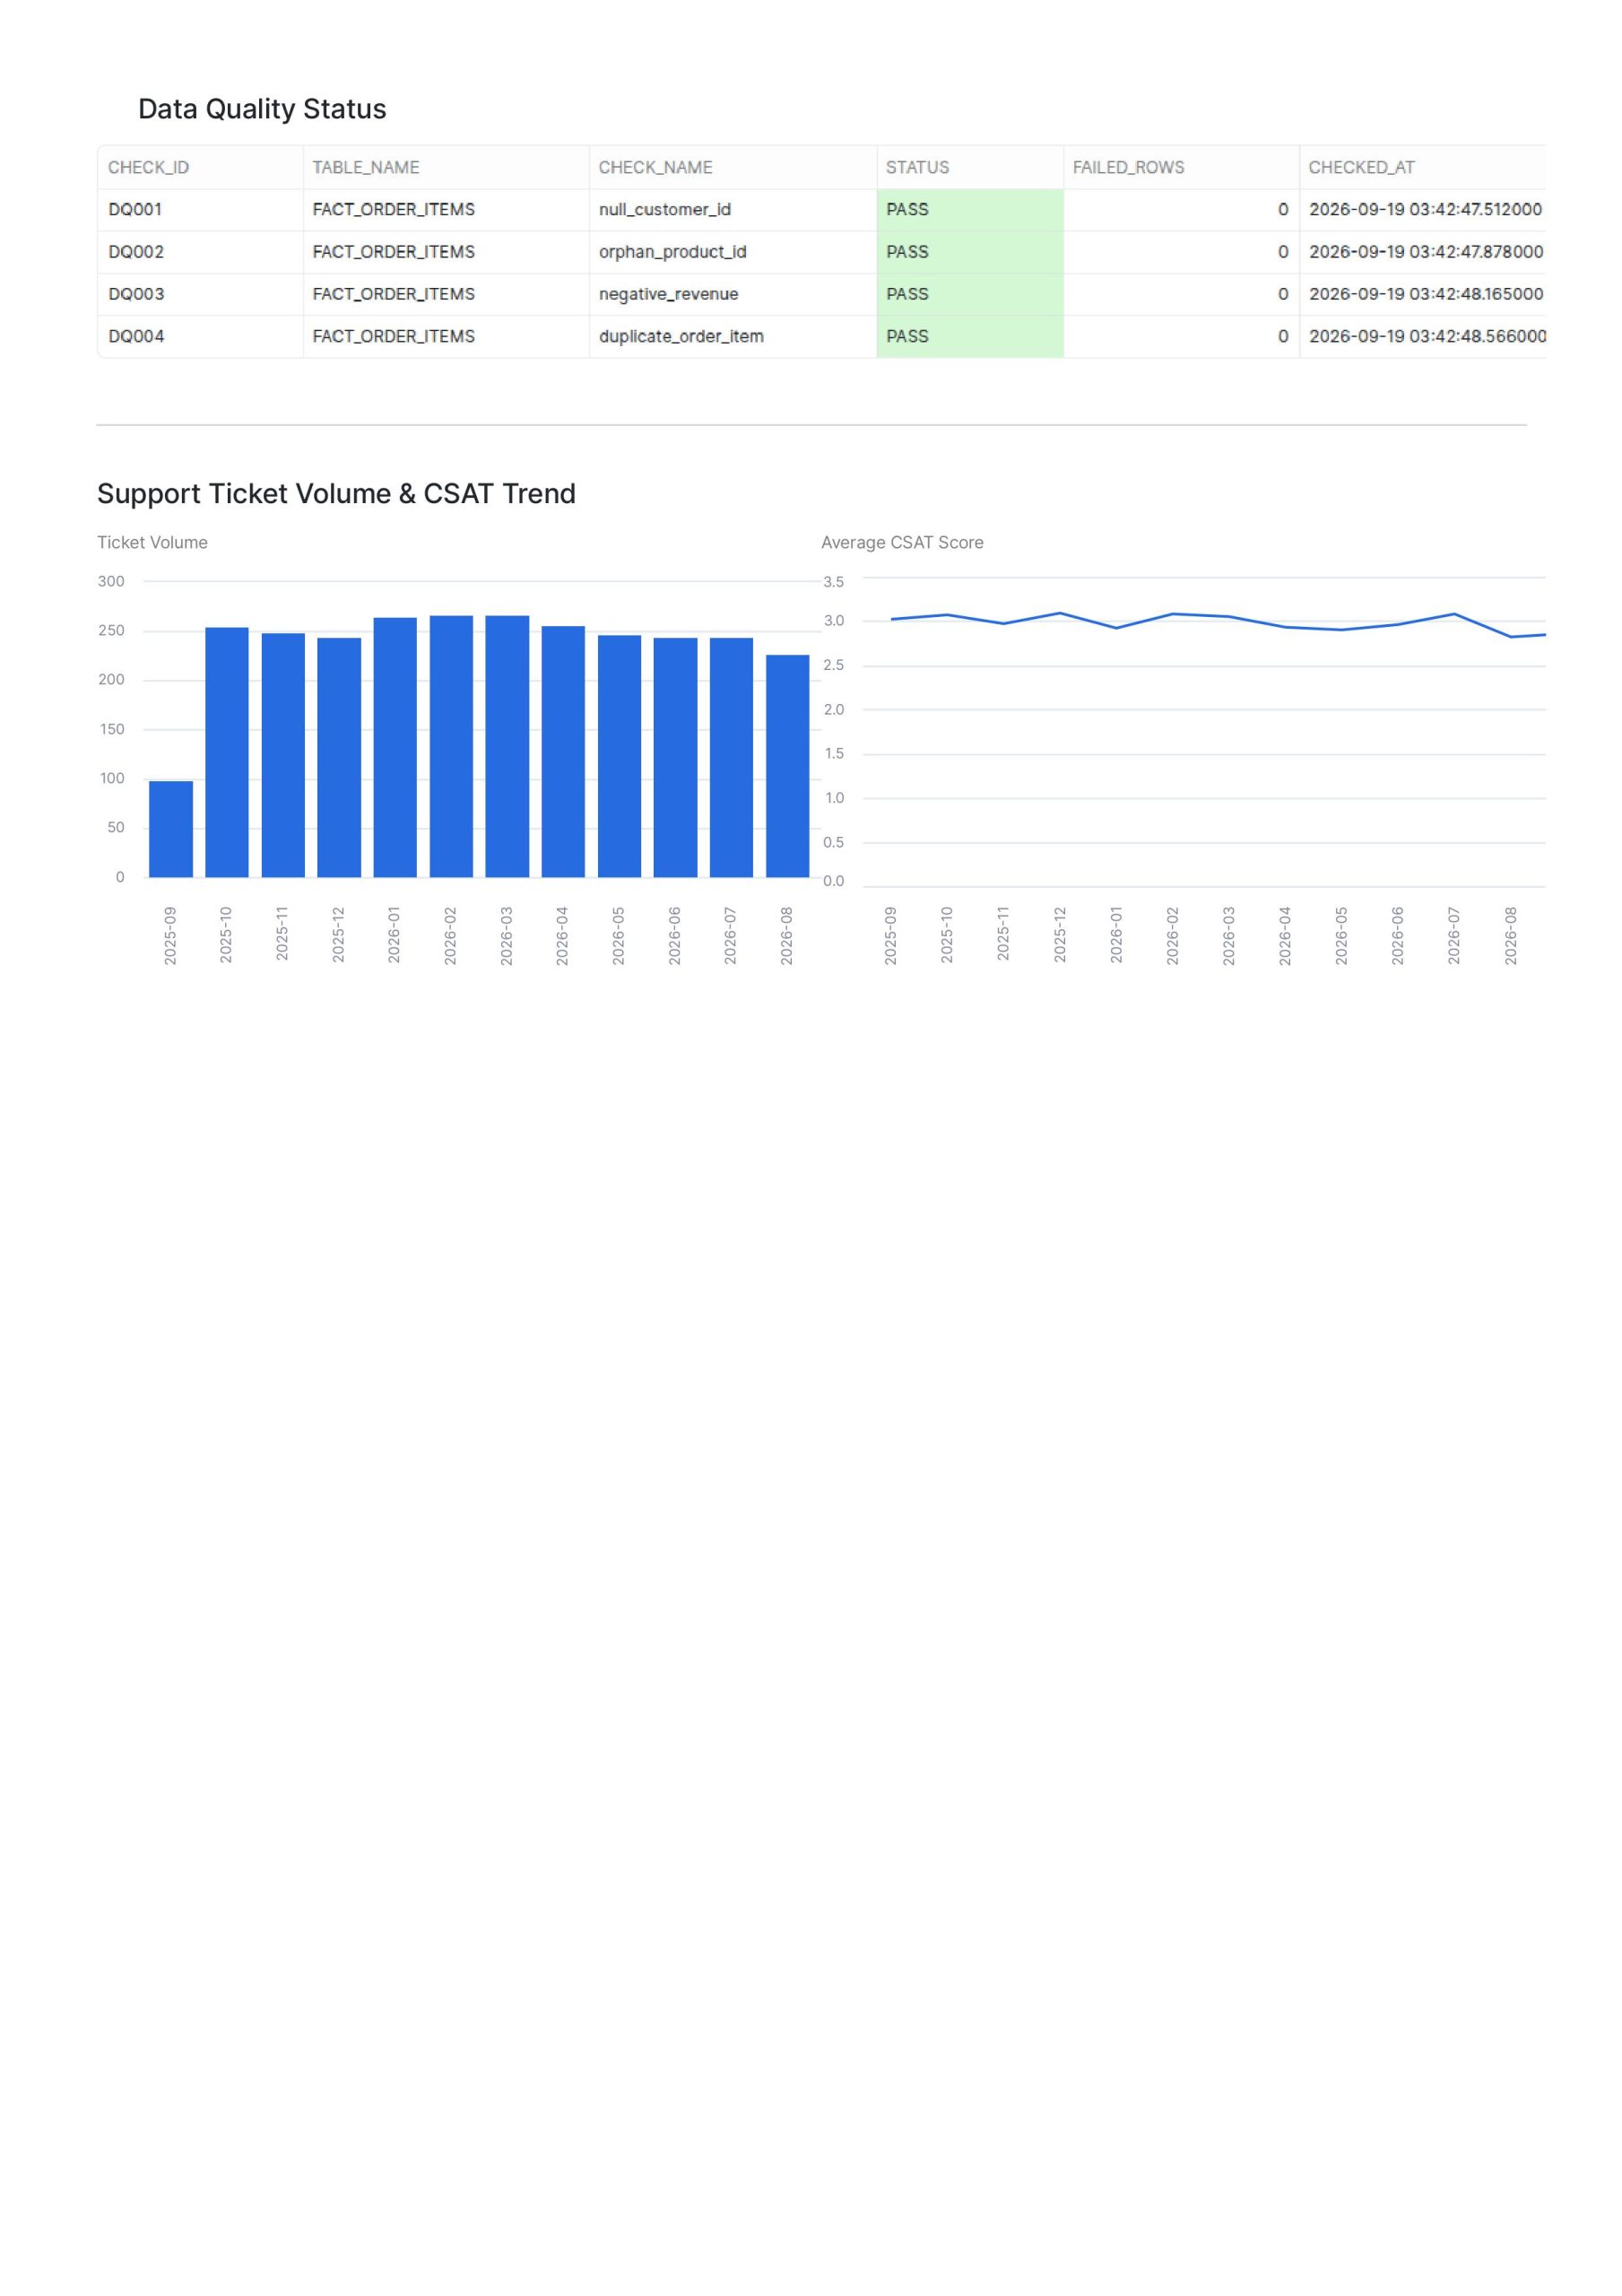
- Automated checks for nulls, referential integrity, duplicates, and invalid values run after every load and are logged centrally
2. Automated Incremental Processing
- Snowflake Streams and Tasks automatically detect and propagate only new or changed data, keeping the platform current without manual reprocessing or full-table reloads.
4. Kimball-Style Star Schema
- Conformed dimensions (customers, products, campaigns, date) and fact tables (order items, returns, support, campaign events) give the business a consistent, query-friendly model that BI tools and analysts can trust.
APPROACH
Our Approach
Architecture-First Design
- We started by mapping the four business questions directly to a target data model, not the other way around.
- This ensured every table and pipeline stage existed to serve a real business answer, not just to store data.
CLI-Driven, Version-Controlled Development
- All environment setup, transformations, and security policies were scripted and run through the Snowflake CLI.
- This made the entire build repeatable, auditable, and ready to hand off to an engineering team via Git.
Incremental, Layer-by-Layer Build
- We built and validated one layer at a time — raw ingestion, then staging, then the star schema, then marts.
- Each layer was checkpointed with row-count and integrity validation before moving to the next, catching issues early.
Automation Over Manual Refresh
- Streams and a Task DAG were introduced early so the pipeline runs on its own schedule, not on-demand.
- This reflects how the platform will actually operate in production, not just how it looks in a one-time demo.
Validate, Then Visualize
- Every mart was checked against its source facts before a single dashboard tile was built.
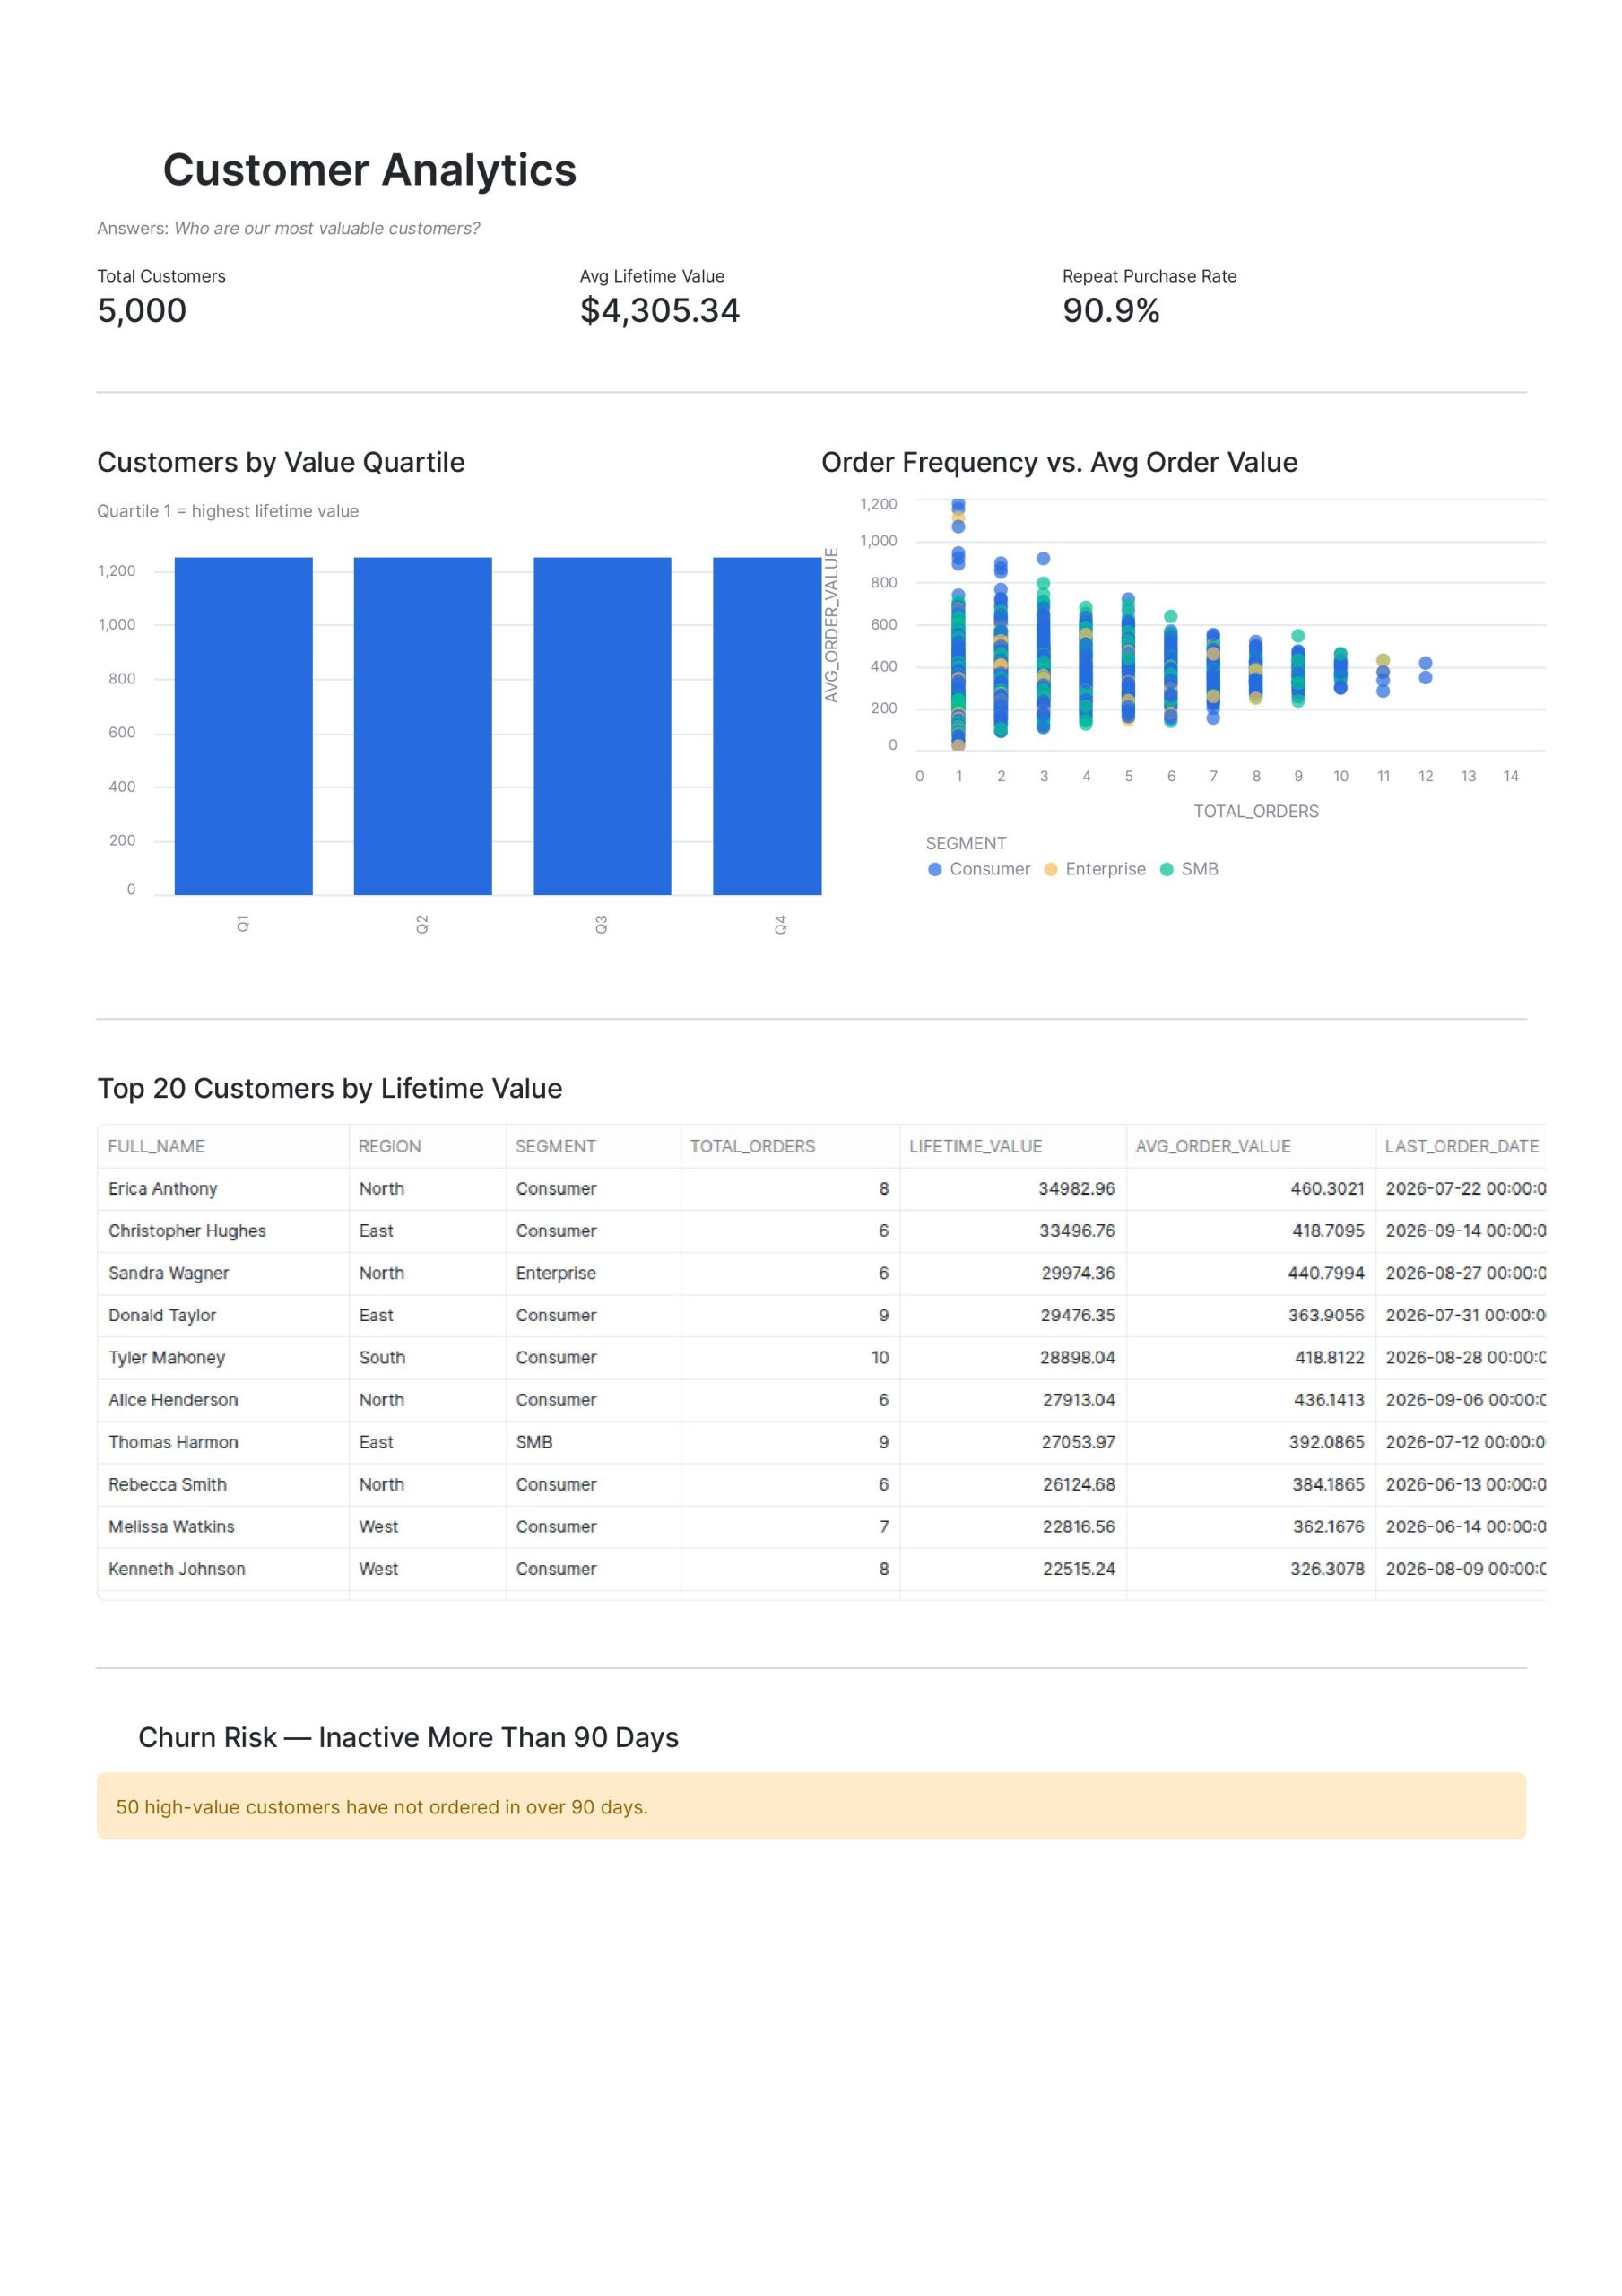
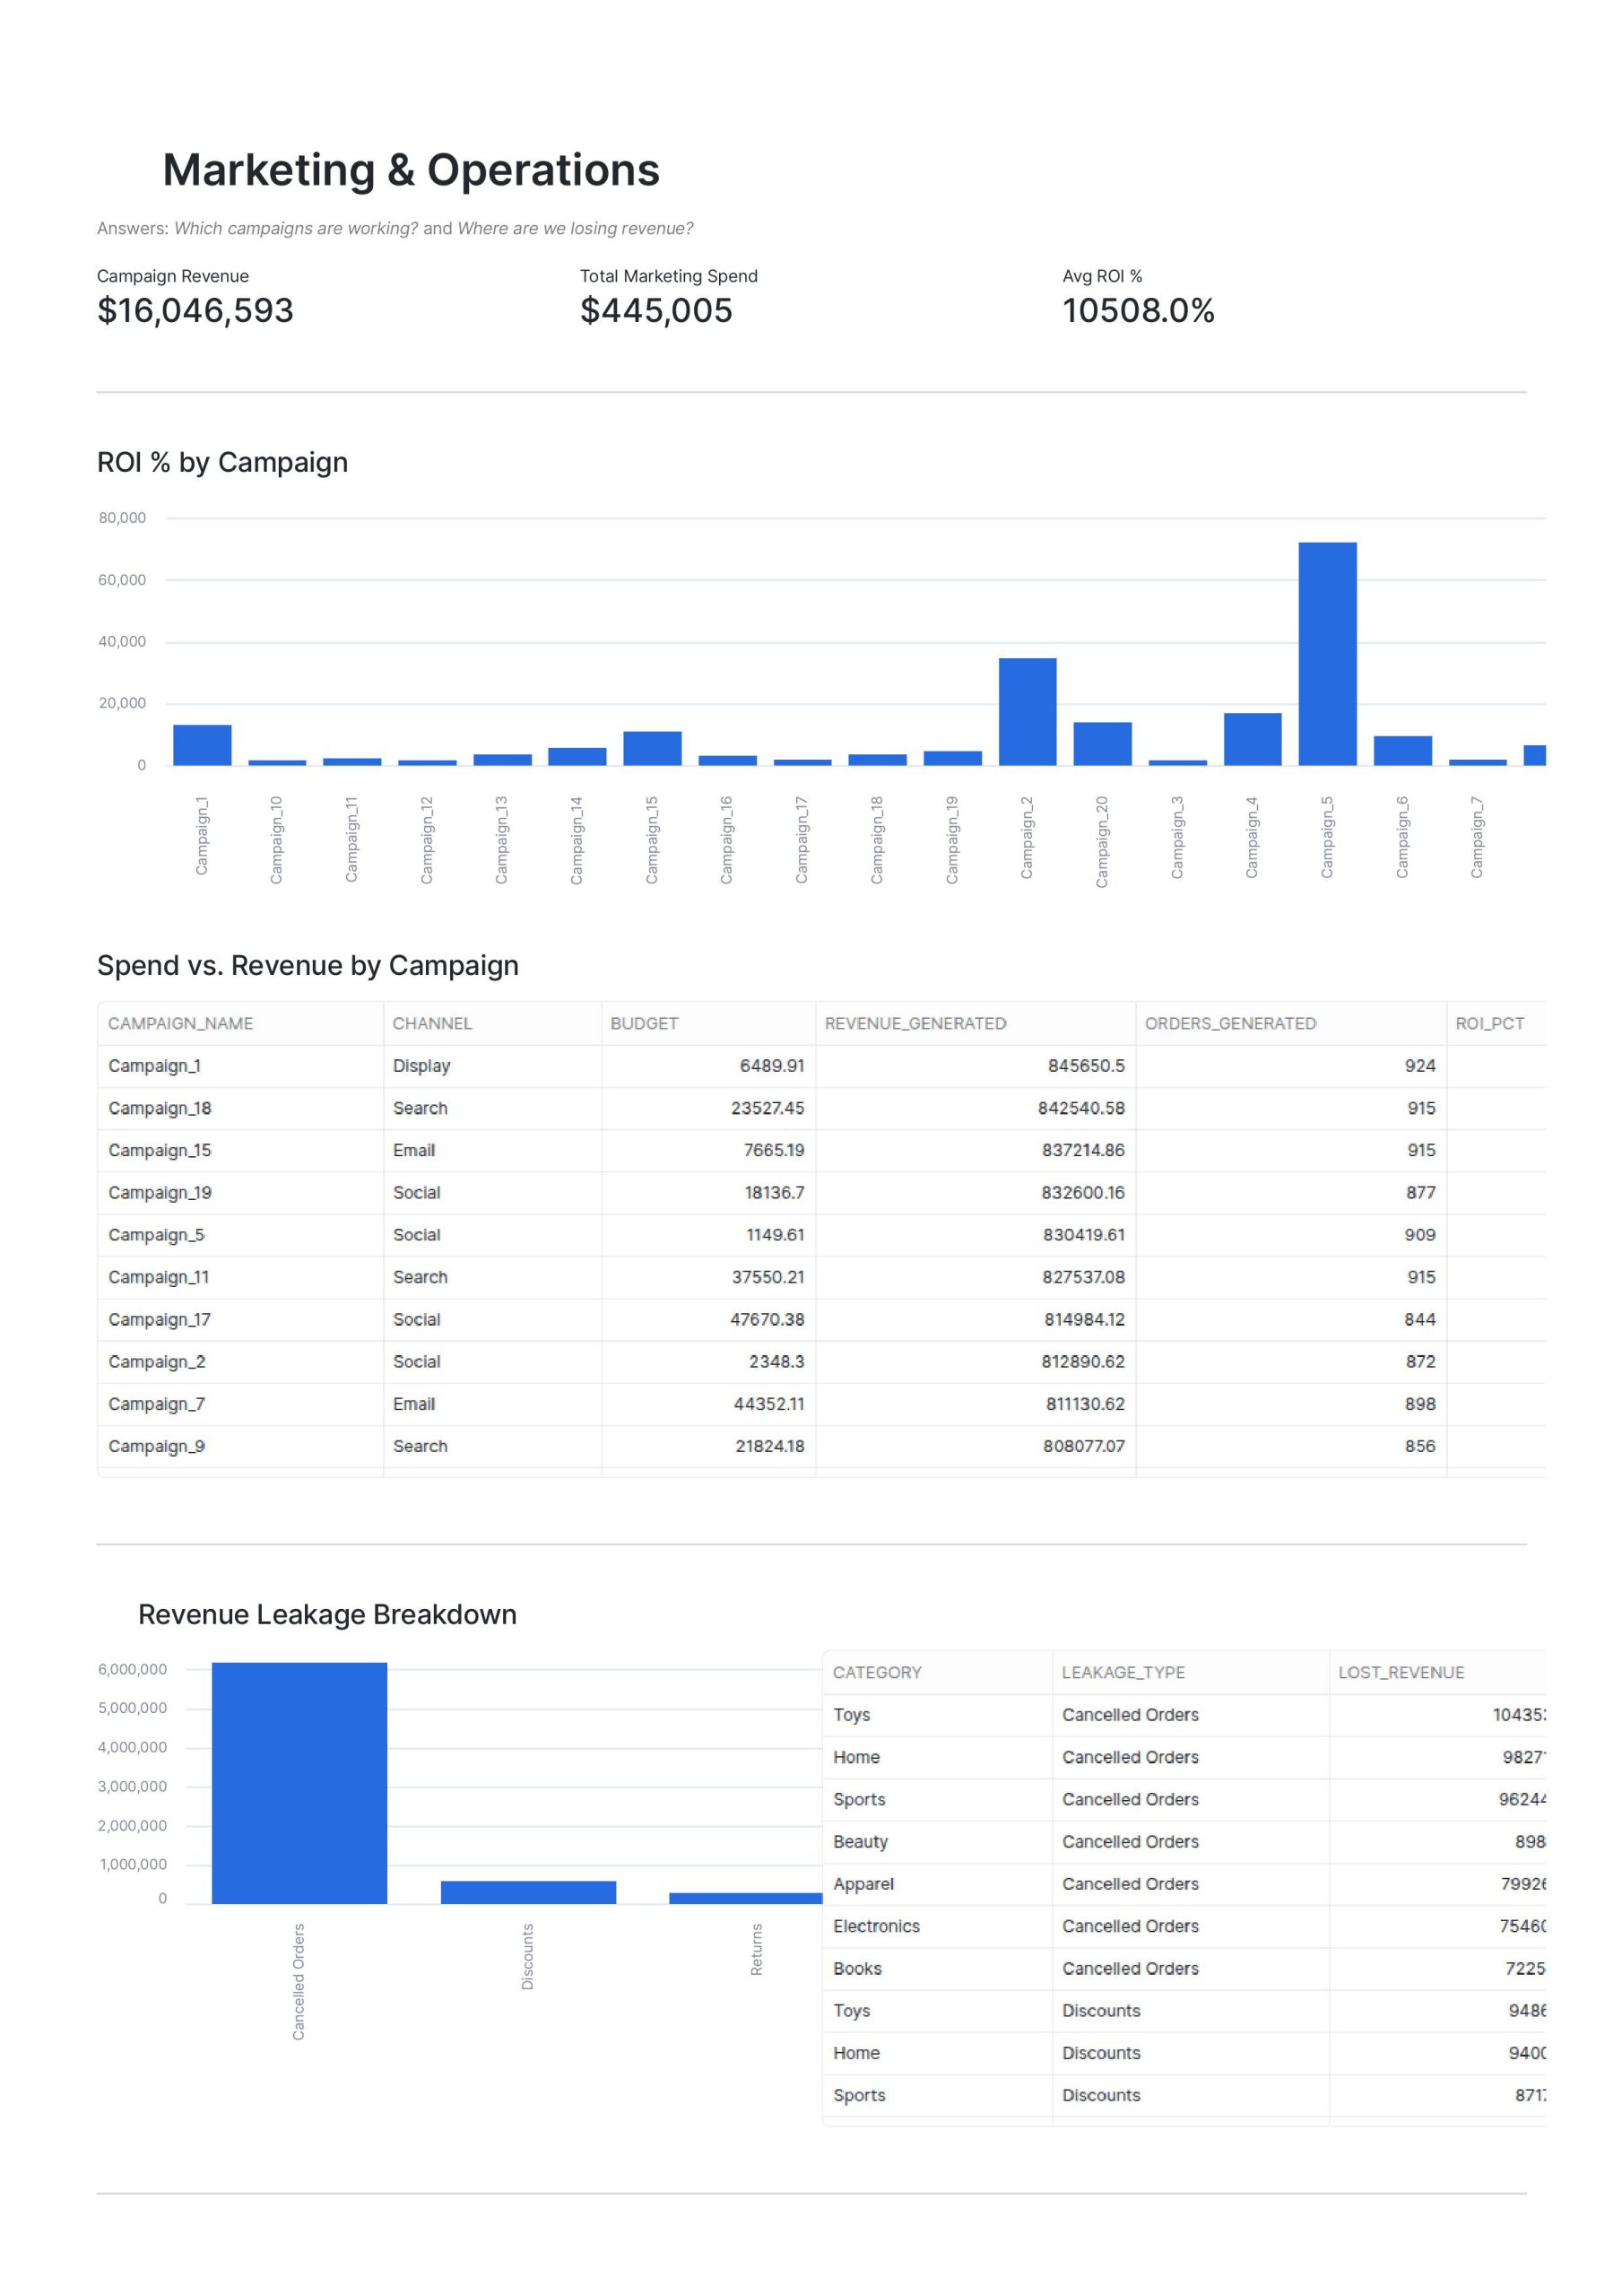
- This meant the three business dashboards were built on already-trusted numbers, not numbers that looked plausible.
SUCCESS AND IMPACT
What Was Achieved
- product, customer, campaign, and financial-leakage data now live in one governed platform instead of scattered spreadsheets and siloed reports
- Product performance made visible
- Customer value quantified
By Business
- Business Documents
- Snowflake Staging
- Data Quality Validation
- Reporting & Analytics